Will FLUX.1 [dev]
run on your GPU?
FLUX, Qwen-Image, Krea 2, Wan, LTX and 45 more. Which file to download, how much VRAM it really needs, and what your card can handle. Sizes from the real files, speed measured in ComfyUI.
I have
and want to run
Real outputs. Real seconds.
 FLUX.1 [dev]FP8 · 1024²36.4s
 Z-Image Turbo16-bit · 1024²11.0s
 Krea 2 TurboINT8 · 1024²10.9s
 Qwen-Image 2.1INT8 · 1024²17.2s
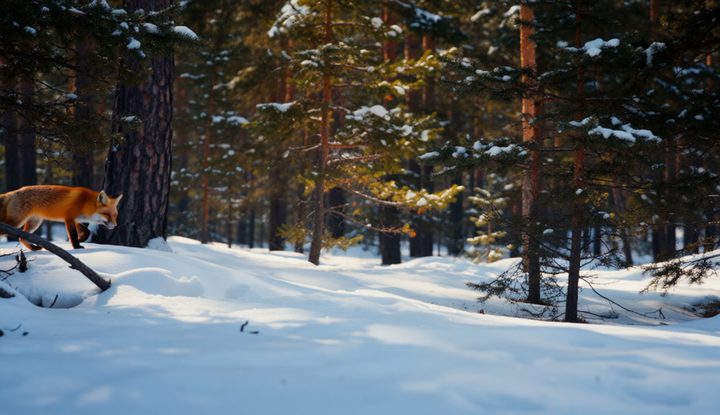 Wan 2.2 T2V 14BFP8 · 832×480 · video19min
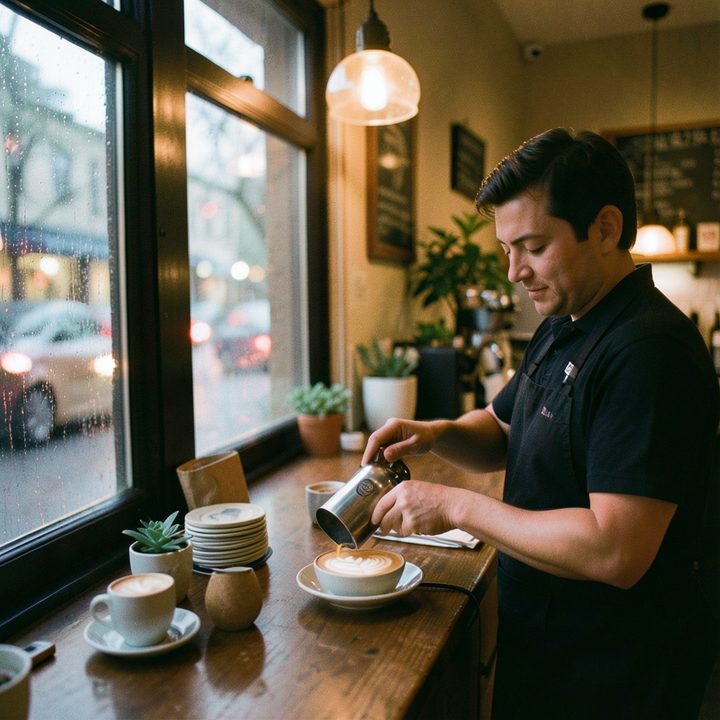 FLUX.2 [klein] 4BFP8 · 1024²2.9s
 Ming-Image DesignINT8 · 1024²7.4s
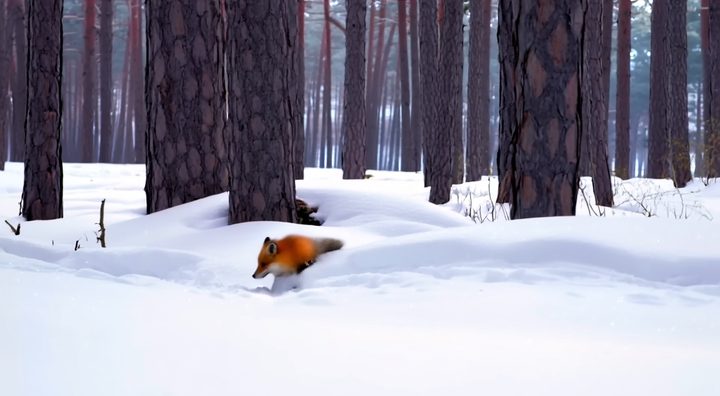 Wan 2.2 TI2V 5B16-bit · 1280×704 · video8.6min
 FLUX.1 KontextFP8 · photo edit53.4s
 FLUX.2 [klein] 9BQ8_0 · 1024²8.5s
- RTX 4060 · 5060 · 3070
- RTX 3060 Ti · 2080 Super
- RX 7600 · 9060 XT 8 GB
- RTX 5070 · 4070 Super
- RTX 3060 12 GB · 4070 Ti
- Arc B580 · RX 7700 XT
- RTX 5060 Ti · 4060 Ti 16 GB
- RTX 5080 · 4080 · 5070 Ti
- RX 9070 XT · 7800 XT
- RTX 4090 · 3090
- RX 7900 XTX
- Arc Pro B60
Every model on one scale. Drag the red line to your VRAM.
The exact workflow behind every number.
19 ComfyUI workflows, saved straight from the runs I measured. Drop the .json on the canvas; the model files are linked on each page.
Browse workflows → Model filesPlan the setting, the upgrade, the laptop
From real file sizes
Every model file is sized to the byte from Hugging Face. Add the model's working memory and a small system reserve, and you get the verdict of what fits entirely.
On my own GPU
I make AI images in ComfyUI on an RTX 5060 Ti 16 GB. A script times each model and logs peak VRAM: 16 models timed so far. See the numbers or get the workflows I used.
From other people
98 real-world results from GitHub, Hugging Face and first-hand blogs, copied as published with a link to each. See them all or send yours.