FLUX.1 [dev] VRAM requirements
The 12B text-to-image model from Black Forest Labs that most local workflows are built around. Strong prompt following and readable text.
01Measured on my RTX 5060 Ti 16 GB
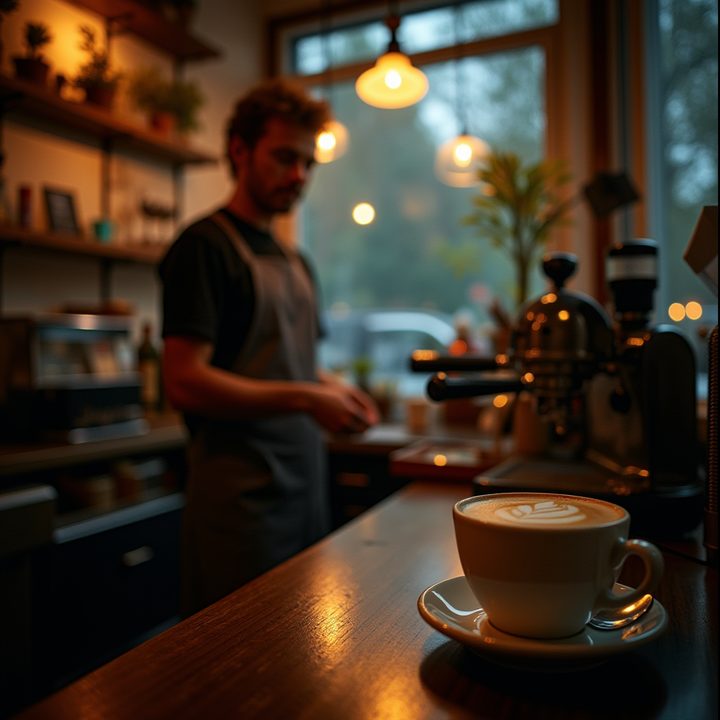
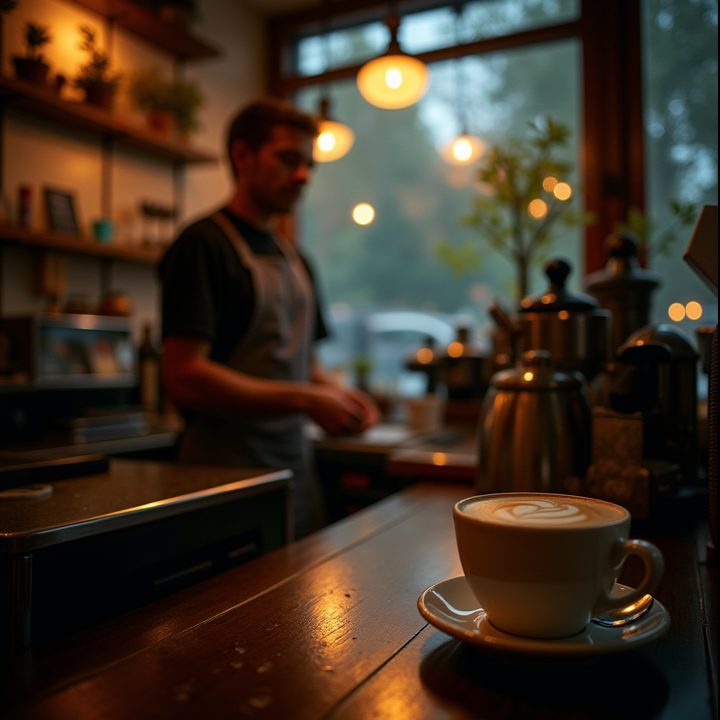
FP8 or GGUF Q8_0: can you see the difference?
Drag the handle. Both images came out of the same workflow on my RTX 5060 Ti 16 GB; only the model file changed.
FP8 workflow GGUF Q8_0 workflow02The files, and how much VRAM each needs
| File | Size | Needed | Min. VRAM | Quality | Source |
|---|---|---|---|---|---|
| 16-bit | 23.8 GB | 26.1 GB | 27 GB | the original weights | black-forest-labs/FLUX.1-dev → |
| Q8_0 | 12.7 GB | 15.0 GB | 16 GB | practically identical to the original | city96/FLUX.1-dev-gguf → |
| FP8 | 11.9 GB | 14.2 GB | 15 GB | practically identical to the original | Kijai/flux-fp8 → |
| Q6_K | 9.9 GB | 12.2 GB | 13 GB | very close to the original | city96/FLUX.1-dev-gguf → |
| Q5_K_S | 8.3 GB | 10.6 GB | 11 GB | close; small differences in fine detail | city96/FLUX.1-dev-gguf → |
| Q4_K_S | 6.8 GB | 9.1 GB | 10 GB | good; some loss in fine detail and text | city96/FLUX.1-dev-gguf → |
| Q3_K_S | 5.2 GB | 7.5 GB | 8 GB | noticeable loss of detail | city96/FLUX.1-dev-gguf → |
| Q2_K | 4.0 GB | 6.3 GB | 7 GB | heavy loss; a last resort | city96/FLUX.1-dev-gguf → |
“Needed” = file + 1.5 GB working memory + 0.8 GB system reserve.
Free ComfyUI workflow, tested on my RTX 5060 Ti: FP8 workflow (.json) · GGUF Q8_0 workflow (.json). Drag the file into ComfyUI. All workflows →
03By amount of VRAM
04Best GPU for FLUX.1 dev
The cheapest cards (by launch price) that run it well, and every card sorted by memory: best GPU for FLUX.1 dev → Planning bigger images or longer clips? Open the calculator →
05By graphics card
| GPU | VRAM | Verdict | Best file | Needed |
|---|---|---|---|---|
| Desktop graphics cards | ||||
| RTX 2060 6 GB | 6 GB | Offload only | Q3_K_S | 7.5 GB |
| RTX 3050 6 GB | 6 GB | Offload only | Q3_K_S | 7.5 GB |
| RTX 2070 Super 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 2080 Super 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 3050 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 3060 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 3060 Ti 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 3070 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 3070 Ti 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 4060 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 4060 Ti 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 5050 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 5060 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 5060 Ti 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RX 7600 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RX 9050 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RX 9060 XT 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| Arc B570 10 GB | 10 GB | Runs | Q4_K_S | 9.1 GB |
| RTX 3080 10 GB | 10 GB | Runs | Q4_K_S | 9.1 GB |
| RTX 2080 Ti 11 GB | 11 GB | Runs | Q5_K_S | 10.6 GB |
| Arc B580 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 2060 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 3060 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 3080 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 3080 Ti 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 4070 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 4070 Super 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 4070 Ti 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 5070 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RX 7700 XT 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RX 9070 GRE 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| Arc A770 16 GB | 16 GB | Runs well | Q8_0 | 15.0 GB |
| RTX 4060 Ti 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RTX 4070 Ti Super 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RTX 4080 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RTX 4080 Super 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RTX 5060 Ti 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RTX 5070 Ti 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RTX 5080 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RX 7600 XT 16 GB | 16 GB | Runs well | Q8_0 | 15.0 GB |
| RX 7800 XT 16 GB | 16 GB | Runs well | Q8_0 | 15.0 GB |
| RX 7900 GRE 16 GB | 16 GB | Runs well | Q8_0 | 15.0 GB |
| RX 9060 XT 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RX 9070 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RX 9070 XT 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RX 7900 XT 20 GB | 20 GB | Runs well | Q8_0 | 15.0 GB |
| Arc Pro B60 24 GB | 24 GB | Runs well | Q8_0 | 15.0 GB |
| RTX 3090 24 GB | 24 GB | Runs well | Q8_0 | 15.0 GB |
| RTX 3090 Ti 24 GB | 24 GB | Runs well | Q8_0 | 15.0 GB |
| RTX 4090 24 GB | 24 GB | Runs well | FP8 | 14.2 GB |
| RX 7900 XTX 24 GB | 24 GB | Runs well | Q8_0 | 15.0 GB |
| Arc Pro B70 32 GB | 32 GB | Runs well | 16-bit | 26.1 GB |
| RTX 5090 32 GB | 32 GB | Runs well | 16-bit | 26.1 GB |
| Laptop GPUs | ||||
| RTX 3050 Laptop 4 GB | 4 GB | Offload only | Q4_K_S | 9.1 GB |
| RTX 3050 Ti Laptop 4 GB | 4 GB | Offload only | Q4_K_S | 9.1 GB |
| RTX 2060 Laptop 6 GB | 6 GB | Offload only | Q3_K_S | 7.5 GB |
| RTX 3050 Laptop 6 GB | 6 GB | Offload only | Q3_K_S | 7.5 GB |
| RTX 3060 Laptop 6 GB | 6 GB | Offload only | Q3_K_S | 7.5 GB |
| RTX 4050 Laptop 6 GB | 6 GB | Offload only | Q3_K_S | 7.5 GB |
| RTX 2070 Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 2070 Super Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 2080 Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 2080 Super Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 3070 Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 3070 Ti Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 3080 Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 4060 Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 4070 Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 5050 Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 5060 Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 5070 Laptop 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RX 7600M 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RX 7600M XT 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RX 7600S 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RX 7700S 8 GB | 8 GB | Tight | Q3_K_S | 7.5 GB |
| RTX 4080 Laptop 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 5070 Laptop 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 5070 Ti Laptop 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RX 7800M 12 GB | 12 GB | Runs | Q5_K_S | 10.6 GB |
| RTX 3080 Laptop 16 GB | 16 GB | Runs well | Q8_0 | 15.0 GB |
| RTX 3080 Ti Laptop 16 GB | 16 GB | Runs well | Q8_0 | 15.0 GB |
| RTX 4090 Laptop 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RTX 5080 Laptop 16 GB | 16 GB | Runs well | FP8 | 14.2 GB |
| RX 7900M 16 GB | 16 GB | Runs well | Q8_0 | 15.0 GB |
| RTX 5090 Laptop 24 GB | 24 GB | Runs well | FP8 | 14.2 GB |
| Unified memory | ||||
| Radeon 8060S (Strix Halo) 96 GB | 96 GB | Runs well | 16-bit | 26.1 GB |
| Radeon 8065S (Gorgon Halo) 160 GB | 160 GB | Runs well | 16-bit | 26.1 GB |
| Apple Silicon Macs (by memory) | ||||
| Mac 16 GB | 12.7 GB | Runs | Q6_K | 12.2 GB |
| Mac 18 GB | 14.4 GB | Runs | Q6_K | 12.2 GB |
| Mac 24 GB | 19.6 GB | Runs well | Q8_0 | 15.0 GB |
| Mac 32 GB | 26.8 GB | Runs well | 16-bit | 26.1 GB |
| Mac 36 GB | 30.2 GB | Runs well | 16-bit | 26.1 GB |
| Mac 48 GB | 40.2 GB | Runs well | 16-bit | 26.1 GB |
| Mac 64 GB | 55.7 GB | Runs well | 16-bit | 26.1 GB |
| Mac 96 GB | 85 GB | Runs well | 16-bit | 26.1 GB |
| Mac 128 GB | 115.4 GB | Runs well | 16-bit | 26.1 GB |
| Mac 192 GB | 175.4 GB | Runs well | 16-bit | 26.1 GB |
| Mac 256 GB | 236.9 GB | Runs well | 16-bit | 26.1 GB |
| Mac 512 GB | 498.1 GB | Runs well | 16-bit | 26.1 GB |
06Text encoder, VAE and other files
| File | Folder | Size | When | |
|---|---|---|---|---|
| CLIP-L clip_l.safetensors | models/text_encoders | 0.2 GB | required | Download → |
| T5-XXL FP8 t5xxl_fp8_e4m3fn.safetensors | models/text_encoders | 4.9 GB | text encoder · smaller, recommended | Download → |
| T5-XXL FP16 t5xxl_fp16.safetensors | models/text_encoders | 9.8 GB | text encoder · alternative | Download → |
| FLUX.1 VAE (ae) ae.safetensors | models/vae | 0.3 GB | required | Download → |
The files the official ComfyUI workflows load next to the model. Sizes read from Hugging Face (2026-10-01).
07Where the files go in ComfyUI
| File | Folder | Loader node |
|---|---|---|
| Diffusion model (.safetensors: 16-bit, FP8, INT8) | ComfyUI/models/diffusion_models | Load Diffusion Model |
| GGUF file (.gguf) | ComfyUI/models/unet | Unet Loader (GGUF) - from the ComfyUI-GGUF node pack |
| Text encoder | ComfyUI/models/text_encoders | Load CLIP / DualCLIPLoader (or the GGUF versions) |
| VAE | ComfyUI/models/vae | Load VAE |
08Measured and reported results
| Label | GPU | Setup | Result | Peak VRAM | Date | Source |
|---|---|---|---|---|---|---|
| measured | RTX 5060 Ti 16 GB | flux1-dev-Q8_0.gguf · 1024x1024 · 20 steps 3 timed runs after 1 warm-up (50.7 s incl. loading). T5-XXL FP8 + CLIP-L, euler/simple, guidance 3.5, ComfyUI 0.25.0 portable, PyTorch 2.12 cu130, 32 GB RAM. Time = sampling + VAE | 40.62 s / image | 15.1 GB | 2026-09-27 | |
| measured | RTX 5060 Ti 16 GB | flux1-dev-Q4_K_S.gguf · 1024x1024 · 20 steps 3 timed runs after 1 warm-up (52.1 s incl. loading). T5-XXL FP8 + CLIP-L, euler/simple, guidance 3.5, ComfyUI 0.25.0 portable, PyTorch 2.12 cu130, 32 GB RAM. Time = sampling + VAE | 47.28 s / image | 8.8 GB | 2026-09-27 | |
| measured | RTX 5060 Ti 16 GB | flux1-dev-fp8.safetensors · 1024x1024 · 20 steps 3 timed runs after 1 warm-up (39.1 s incl. loading). T5-XXL FP8 + CLIP-L, euler/simple, guidance 3.5, ComfyUI 0.25.0 portable, PyTorch 2.12 cu130, 32 GB RAM. Time = sampling + VAE | 36.36 s / image | 14.8 GB | 2026-09-27 | |
| reported | Arc A770 16 GB | fp8 (ComfyUI template) · 20 steps “20/20 [00:46<00:00, 2.33s/it] Prompt executed in 47.13 seconds” 'GPU Benchmark Flux DEV fp8' thread; Intel A770 on Fedora Linux, PyTorch 2.3.110+xpu (53.26 s with PyTorch nightly); resolution not stated | 47.13 s / image · 2.33 s/it | — | 2025-07-24 | github.com → |
| reported | Arc B580 12 GB | fp8 · 1024x1024 · 20 steps “Flux1 dev fp8 (20step): GOOD (35s)” Intel Arc B580 12GB, PyTorch 2.8 XPU in Docker (YanWenKun); single 1024x1024 image, pre-warmed inference only (model load excluded) | 35 s / image | — | 2025-08-03 | github.com → |
| reported | Radeon 8060S (Strix Halo) 96 GB | flux1-dev full precision (23.8 GB) + t5xxl_fp16 · 1024x1024 · 20 steps “Steady state | 3.64 s/it | 77.56 s” AMD ROCm blog, Ryzen AI Max+ 395 / Radeon 8060S, 128 GB unified, Windows ComfyUI; first run 103.89 s; vendor-published measurement | 77.56 s / image · 3.64 s/it | — | 2026-07-14 | rocm.blogs.amd.com → |
| reported | RTX 3090 24 GB | fp8 (ComfyUI template) “Nvidia 3090: 26s” ComfyUI 'GPU Benchmark Flux DEV fp8' thread: stock Flux dev fp8 workflow template, time of 2nd/3rd run (no loading); resolution/steps not stated in thread | 26 s / image | — | 2025-07-22 | github.com → |
| reported | RTX 4060 Ti 16 GB | FP8 “Flux-Dev(FP8) … 2回目は72秒から51秒とあまり効果が感じられませんでした。” ComfyUI; same PC before/after swapping RTX 4060 Ti 8GB -> 16GB; 2nd-run times; resolution/steps not stated; 51 s = 16GB card | 51 s / image | — | 2025-01-03 | note.com → |
| reported | RTX 4060 Ti 8 GB | FP8 “Flux-Dev(FP8) … 2回目は72秒から51秒とあまり効果が感じられませんでした。” ComfyUI; same PC before/after swapping RTX 4060 Ti 8GB -> 16GB; 2nd-run times; resolution/steps not stated; 72 s = 8GB card | 72 s / image | — | 2025-01-03 | note.com → |
| reported | RTX 4070 Super 12 GB | Q4_0 GGUF “1.9s/it with Q4_0” RTX 4070 Super 12GB; same post: 2.6s/it with Q5_1, 1.3s/it with NF4; resolution not stated; early (Aug 2024) ComfyUI-GGUF | 1.9 s/it | — | 2024-08-17 | huggingface.co → |
| reported | RTX 4080 16 GB | fp8_e4m3fn weight_dtype · 1024x1024 · 20 steps “weight_dtype (fp8_e4m3fn) with --fast (13sec)” ComfyUI 'RTX 4090 benchmarks - FLUX model' thread; OP settings 1024x1024, 20 steps; Aug 2024 ComfyUI/PyTorch 2.5 dev; with --fast flag (same poster: 19sec without --fast, 28sec def | 13 s / image | — | 2024-08-23 | github.com → |
| reported | RTX 4090 24 GB | fp8 (ComfyUI template) “Prompt executed in 11.28 seconds” ComfyUI 'GPU Benchmark Flux DEV fp8' thread: stock Flux dev fp8 workflow template, time of 2nd/3rd run (no loading); resolution/steps not stated in thread | 11.28 s / image | — | 2025-12-28 | github.com → |
| reported | RTX 4090 24 GB | Q8_0 GGUF · 1024x1024 · 20 steps “15 seconds at the fastest to 17 seconds at the slowest on my RTX 4090 with Euler 20 Steps for 1024x1024 images” stated range 15-17 s; city96 ComfyUI-GGUF Q8 | 15 s / image | — | 2024-08-25 | github.com → |
| reported | RTX 4090 24 GB | fp8 (--fast) · 1024x1024 · 20 steps “Prompt executed in 10.01 seconds” ComfyUI 'RTX 4090 benchmarks - FLUX model' thread; OP settings 1024x1024, 20 steps; Aug 2024 ComfyUI/PyTorch 2.5 dev; FP8 with --fast, GPU at 2.52 GHz/875mV undervolt (9.07 s at 2. | 10.01 s / image | — | 2024-08-26 | github.com → |
| reported | RTX 5060 Ti 16 GB | fp8 (ComfyUI template) “Prompt executed in 25.71 seconds” ComfyUI 'GPU Benchmark Flux DEV fp8' thread: stock Flux dev fp8 workflow template, time of 2nd/3rd run (no loading); resolution/steps not stated in thread; poster's log shows 16311 | 25.71 s / image | — | 2025-08-04 | github.com → |
| reported | RTX 5090 32 GB | fp8 (ComfyUI template) “Getting 8.78s at 2.38it/s for 3 runs.” ComfyUI 'GPU Benchmark Flux DEV fp8' thread: stock Flux dev fp8 workflow template, time of 2nd/3rd run (no loading); resolution/steps not stated in thread; Inno3D RTX 5090 X3 OC | 8.78 s / image · 2.38 it/s | — | 2025-08-05 | github.com → |
Other people's numbers are copied as published, with a link. Send yours.
09Training a LoRA for FLUX.1 dev
| Trainer | VRAM | Type | Settings and quote | Source |
|---|---|---|---|---|
| sd-scripts | 8 GB | stated minimum | --fp8_base, --blocks_to_swap 28, fp8 T5XXL recommended; table also: 24GB batch 2, 16GB batch 1 + swap, 12GB swap 16 + AdamW8bit, 10GB swap 22 “8GB VRAM: Use --blocks_to_swap 28, recommend fp8 format for T5XXL” | github.com → |
| SimpleTuner | 10 GB | stated minimum | Rank-16 LoRA; NF4 base ~9 GB (int8 ~18 GB, int4 ~13 GB, unquantised ~30 GB); lowest config 512px, batch 1, Lion8bit paged; 1024px needs >=12 GB. Guide example uses FLUX.1 Krea “the absolute minimum is a single 3080 10G” | github.com → |
| fluxgym | 12 GB | stated minimum | 12G preset: kohya sd-scripts backend, --fp8_base, Adafactor, --split_mode, train_blocks=single, gradient checkpointing, cached TE outputs; default 512px, rank 4 “Dead simple web UI for training FLUX LoRA with LOW VRAM (12GB/16GB/20GB) support.” | github.com → |
| OneTrainer | 12 GB | stated minimum | Wiki Flux page; no specific settings given (NF4/fp8 mentioned nearby); 8GB possible with GGUF “It is possible to train a Flux Lora on a GPU with 12GB of VRAM.” | github.com → |
| ai-toolkit | 24 GB | stated minimum | Historical README requirement (removed from README on 2026-03-31 in commit ad474e3); 8-bit quantized base, low_vram flag if GPU drives monitors “You currently need a GPU with at least 24GB of VRAM to train FLUX.1.” | github.com → |
| ai-toolkit | 24 GB | example run | Current official example config: rank 16, batch 1, 512/768/1024 buckets, gradient checkpointing, quantize: true (8-bit); README still points to this file “Copy the example config file located at config/examples/train_lora_flux_24gb.yaml” | github.com → |
reported From each trainer's own docs, 2026-09-25. Why the figures differ →
10Every file tracked for FLUX.1 dev
| File | Type | Size | Repo |
|---|---|---|---|
| flux1-dev-fp8-e4m3fn.safetensors | FP8 | 11.90 GB | Kijai/flux-fp8 → |
| flux1-dev-fp8-e5m2.safetensors | FP8 | 11.90 GB | Kijai/flux-fp8 → |
| flux1-dev.safetensors | BF16 | 23.80 GB | black-forest-labs/FLUX.1-dev → |
| flux1-dev-F16.gguf | F16 | 23.80 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q8_0.gguf | Q8_0 | 12.71 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q6_K.gguf | Q6_K | 9.86 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q5_1.gguf | Q5_1 | 9.01 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q5_K_S.gguf | Q5_K_S | 8.29 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q5_0.gguf | Q5_0 | 8.27 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q4_1.gguf | Q4_1 | 7.53 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q4_K_S.gguf | Q4_K_S | 6.81 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q4_0.gguf | Q4_0 | 6.79 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q3_K_S.gguf | Q3_K_S | 5.23 GB | city96/FLUX.1-dev-gguf → |
| flux1-dev-Q2_K.gguf | Q2_K | 4.03 GB | city96/FLUX.1-dev-gguf → |
Text encoders: clip_l + T5-XXL. VAE ae.safetensors 335304388 bytes (BFL repo).