Wan 2.2 T2V A14B VRAM requirements
Wan 2.2 splits the work between two 14B models: one for the early, noisy steps and one for the late ones. Only one needs to be in VRAM at a time, but both must fit in system RAM.
01Measured on my RTX 5060 Ti 16 GB
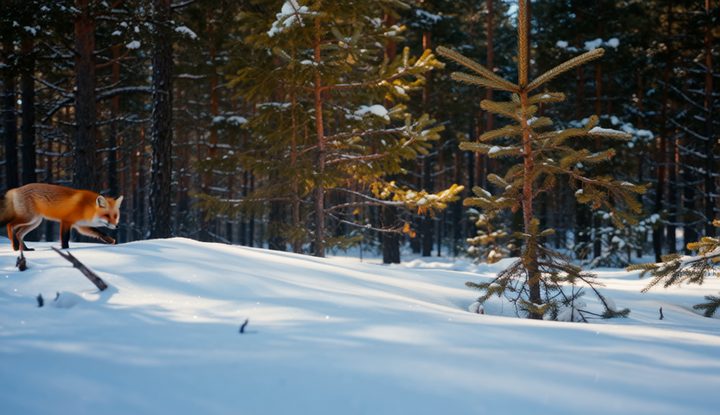
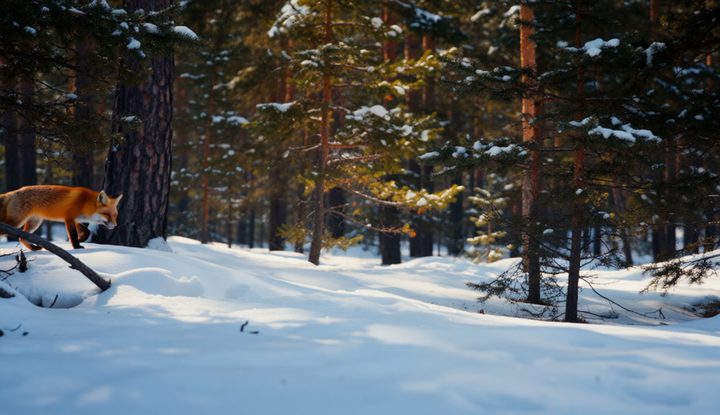
FP8 or GGUF Q5_K_M: can you see the difference?
Drag the handle. Both images came out of the same workflow on my RTX 5060 Ti 16 GB; only the model file changed.
FP8 workflow GGUF Q5_K_M workflow02The files, and how much VRAM each needs
| File | Size | Needed | Min. VRAM | Quality | Source |
|---|---|---|---|---|---|
| 16-bit | 28.6 GB | 32.9 GB | 33 GB | the original weights | Comfy-Org/Wan_2.2_ComfyUI_Repackaged → |
| Q8_0 | 15.4 GB | 19.7 GB | 20 GB | practically identical to the original | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| FP8 | 14.3 GB | 18.6 GB | 19 GB | practically identical to the original | Comfy-Org/Wan_2.2_ComfyUI_Repackaged → |
| Q6_K | 12.0 GB | 16.3 GB | 17 GB | very close to the original | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Q5_K_M | 10.8 GB | 15.1 GB | 16 GB | close; small differences in fine detail | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Q4_K_M | 9.7 GB | 14.0 GB | 14 GB | good; some loss in fine detail and text | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Q3_K_M | 7.2 GB | 11.5 GB | 12 GB | noticeable loss of detail | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Q2_K | 5.3 GB | 9.6 GB | 10 GB | heavy loss; a last resort | QuantStack/Wan2.2-T2V-A14B-GGUF → |
“Needed” = file + 3.5 GB working memory + 0.8 GB system reserve. Wan 2.2 A14B uses two files of this size; only one sits in VRAM at a time, both must fit in system RAM.
Free ComfyUI workflow, tested on my RTX 5060 Ti: FP8 workflow (.json) · GGUF Q5_K_M workflow (.json). Drag the file into ComfyUI. All workflows →
03By amount of VRAM
04Best GPU for Wan 2.2 T2V
The cheapest cards (by launch price) that run it well, and every card sorted by memory: best GPU for Wan 2.2 T2V → Planning bigger images or longer clips? Open the calculator →
05By graphics card
| GPU | VRAM | Verdict | Best file | Needed |
|---|---|---|---|---|
| Desktop graphics cards | ||||
| RTX 2060 6 GB | 6 GB | Offload only | Q4_K_M | 14.0 GB |
| RTX 3050 6 GB | 6 GB | Offload only | Q4_K_M | 14.0 GB |
| RTX 2070 Super 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 2080 Super 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 3050 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 3060 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 3060 Ti 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 3070 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 3070 Ti 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 4060 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 4060 Ti 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 5050 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 5060 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 5060 Ti 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RX 7600 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RX 9050 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RX 9060 XT 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| Arc B570 10 GB | 10 GB | Tight | Q2_K | 9.6 GB |
| RTX 3080 10 GB | 10 GB | Tight | Q2_K | 9.6 GB |
| RTX 2080 Ti 11 GB | 11 GB | Tight | Q2_K | 9.6 GB |
| Arc B580 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 2060 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 3060 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 3080 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 3080 Ti 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 4070 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 4070 Super 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 4070 Ti 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 5070 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RX 7700 XT 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RX 9070 GRE 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| Arc A770 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 4060 Ti 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 4070 Ti Super 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 4080 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 4080 Super 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 5060 Ti 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 5070 Ti 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 5080 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RX 7600 XT 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RX 7800 XT 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RX 7900 GRE 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RX 9060 XT 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RX 9070 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RX 9070 XT 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RX 7900 XT 20 GB | 20 GB | Runs well | Q8_0 | 19.7 GB |
| Arc Pro B60 24 GB | 24 GB | Runs well | Q8_0 | 19.7 GB |
| RTX 3090 24 GB | 24 GB | Runs well | Q8_0 | 19.7 GB |
| RTX 3090 Ti 24 GB | 24 GB | Runs well | Q8_0 | 19.7 GB |
| RTX 4090 24 GB | 24 GB | Runs well | FP8 | 18.6 GB |
| RX 7900 XTX 24 GB | 24 GB | Runs well | Q8_0 | 19.7 GB |
| Arc Pro B70 32 GB | 32 GB | Runs well | Q8_0 | 19.7 GB |
| RTX 5090 32 GB | 32 GB | Runs well | FP8 | 18.6 GB |
| Laptop GPUs | ||||
| RTX 3050 Laptop 4 GB | 4 GB | Not practical | Q2_K | 9.6 GB |
| RTX 3050 Ti Laptop 4 GB | 4 GB | Not practical | Q2_K | 9.6 GB |
| RTX 2060 Laptop 6 GB | 6 GB | Offload only | Q4_K_M | 14.0 GB |
| RTX 3050 Laptop 6 GB | 6 GB | Offload only | Q4_K_M | 14.0 GB |
| RTX 3060 Laptop 6 GB | 6 GB | Offload only | Q4_K_M | 14.0 GB |
| RTX 4050 Laptop 6 GB | 6 GB | Offload only | Q4_K_M | 14.0 GB |
| RTX 2070 Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 2070 Super Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 2080 Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 2080 Super Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 3070 Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 3070 Ti Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 3080 Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 4060 Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 4070 Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 5050 Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 5060 Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 5070 Laptop 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RX 7600M 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RX 7600M XT 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RX 7600S 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RX 7700S 8 GB | 8 GB | Offload only | Q2_K | 9.6 GB |
| RTX 4080 Laptop 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 5070 Laptop 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 5070 Ti Laptop 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RX 7800M 12 GB | 12 GB | Tight | Q3_K_M | 11.5 GB |
| RTX 3080 Laptop 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 3080 Ti Laptop 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 4090 Laptop 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 5080 Laptop 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RX 7900M 16 GB | 16 GB | Runs | Q5_K_M | 15.1 GB |
| RTX 5090 Laptop 24 GB | 24 GB | Runs well | FP8 | 18.6 GB |
| Unified memory | ||||
| Radeon 8060S (Strix Halo) 96 GB | 96 GB | Runs well | 16-bit | 32.9 GB |
| Radeon 8065S (Gorgon Halo) 160 GB | 160 GB | Runs well | 16-bit | 32.9 GB |
| Apple Silicon Macs (by memory) | ||||
| Mac 16 GB | 12.7 GB | Tight | Q3_K_M | 11.5 GB |
| Mac 18 GB | 14.4 GB | Runs | Q4_K_M | 14.0 GB |
| Mac 24 GB | 19.6 GB | Runs | Q6_K | 16.3 GB |
| Mac 32 GB | 26.8 GB | Runs well | Q8_0 | 19.7 GB |
| Mac 36 GB | 30.2 GB | Runs well | Q8_0 | 19.7 GB |
| Mac 48 GB | 40.2 GB | Runs well | 16-bit | 32.9 GB |
| Mac 64 GB | 55.7 GB | Runs well | 16-bit | 32.9 GB |
| Mac 96 GB | 85 GB | Runs well | 16-bit | 32.9 GB |
| Mac 128 GB | 115.4 GB | Runs well | 16-bit | 32.9 GB |
| Mac 192 GB | 175.4 GB | Runs well | 16-bit | 32.9 GB |
| Mac 256 GB | 236.9 GB | Runs well | 16-bit | 32.9 GB |
| Mac 512 GB | 498.1 GB | Runs well | 16-bit | 32.9 GB |
06Text encoder, VAE and other files
| File | Folder | Size | When | |
|---|---|---|---|---|
| UMT5-XXL FP8 (scaled) umt5_xxl_fp8_e4m3fn_scaled.safetensors | models/text_encoders | 6.7 GB | text encoder · smaller, recommended | Download → |
| UMT5-XXL FP16 umt5_xxl_fp16.safetensors | models/text_encoders | 11.4 GB | text encoder · alternative | Download → |
| Wan 2.1 VAE wan_2.1_vae.safetensors | models/vae | 0.3 GB | required | Download → |
The files the official ComfyUI workflows load next to the model. Sizes read from Hugging Face (2026-10-01).
07Where the files go in ComfyUI
| File | Folder | Loader node |
|---|---|---|
| Diffusion model (.safetensors: 16-bit, FP8, INT8) | ComfyUI/models/diffusion_models | Load Diffusion Model |
| GGUF file (.gguf) | ComfyUI/models/unet | Unet Loader (GGUF) - from the ComfyUI-GGUF node pack |
| Text encoder | ComfyUI/models/text_encoders | Load CLIP / DualCLIPLoader (or the GGUF versions) |
| VAE | ComfyUI/models/vae | Load VAE |
08Measured and reported results
| Label | GPU | Setup | Result | Peak VRAM | Date | Source |
|---|---|---|---|---|---|---|
| measured | RTX 5060 Ti 16 GB | wan2.2_t2v_high/low_noise_14B_fp8_scaled.safetensors · 832x480 · 20 steps 1 timed run after 1 warm-up (1149.4 s). Peak RAM 28.6 GB. ComfyUI 0.25.0 portable, PyTorch 2.12 cu130, 32 GB RAM. Text to video, 81 frames (about 5 s), 832x480, 20 steps (10 high-n | 1146.1 s / clip (81 frames) | 13.3 GB | 2026-09-27 | |
| measured | RTX 5060 Ti 16 GB | Wan2.2-T2V-A14B-HighNoise/LowNoise-Q5_K_M.gguf · 832x480 · 20 steps 2 timed runs (1535.0, 1544.5 s) after 1 warm-up (1538.7 s). Peak RAM 33.1 GB. ComfyUI 0.25.0 portable, PyTorch 2.12 cu130, 32 GB RAM. Text to video, 81 frames (about 5 s), 832x480, | 1539.8 s / clip (81 frames) | 14.0 GB | 2026-09-27 | |
| measured | RTX 5060 Ti 16 GB | Wan2.2-T2V-A14B-HighNoise/LowNoise-Q8_0.gguf · 832x480 · 20 steps 1 timed run after 1 warm-up (1516.6 s). Peak RAM 32.9 GB (warm-up), 31.9 GB (timed run). ComfyUI 0.25.0 portable, PyTorch 2.12 cu130, 32 GB RAM. Text to video, 81 frames (about 5 s | 1515.9 s / clip (81 frames) | 13.1 GB | 2026-09-27 | |
| reported | Radeon 8060S (Strix Halo) 96 GB | Wan 2.2 T2V A14B (high+low noise experts) · 640x640 · 4 steps “Steady state | 197 s/it | 186 s/it | 26 min 51 s” AMD ROCm blog, Ryzen AI Max+ 395; s/it for high-noise / low-noise expert; 26 min 51 s = 1611 s; first run 36 min 14 s; vendor-published | 1611 s / clip (81 frames) | — | 2026-07-14 | rocm.blogs.amd.com → |
Other people's numbers are copied as published, with a link. Send yours.
09Training a LoRA for Wan 2.2 T2V
| Trainer | VRAM | Type | Settings and quote | Source |
|---|---|---|---|---|
| ai-toolkit | 24 GB | example run | Official example config (image training, num_frames 1): 4-bit (uint4) base with accuracy recovery adapter, fp8 TE, cached text embeddings, low_vram, rank 32, 512-1024px “# required for 24GB cards. You must do either unload_text_encoder or cache_text_embeddings but not both” | github.com → |
| musubi-tuner | 24 GB | stated minimum | Same Wan doc statement as Wan 2.1 (Wan 2.2 14B supported): 720x1280 images, fp8 + block swap “training with 720x1280 images with 24GB VRAM” | github.com → |
reported From each trainer's own docs, 2026-09-25. Why the figures differ →
10Every file tracked for Wan 2.2 T2V
| File | Type | Size | Repo |
|---|---|---|---|
| wan2.2_t2v_high_noise_14B_fp16.safetensors (high_noise) | F16 | 28.58 GB | Comfy-Org/Wan_2.2_ComfyUI_Repackaged → |
| wan2.2_t2v_low_noise_14B_fp16.safetensors (low_noise) | F16 | 28.58 GB | Comfy-Org/Wan_2.2_ComfyUI_Repackaged → |
| wan2.2_t2v_high_noise_14B_fp8_scaled.safetensors (high_noise) | FP8 | 14.29 GB | Comfy-Org/Wan_2.2_ComfyUI_Repackaged → |
| wan2.2_t2v_low_noise_14B_fp8_scaled.safetensors (low_noise) | FP8 | 14.29 GB | Comfy-Org/Wan_2.2_ComfyUI_Repackaged → |
| Wan2.2-T2V-A14B-HighNoise-Q8_0.gguf (high_noise) | Q8_0 | 15.40 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q8_0.gguf (low_noise) | Q8_0 | 15.40 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q6_K.gguf (high_noise) | Q6_K | 12.00 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q6_K.gguf (low_noise) | Q6_K | 12.00 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q5_1.gguf (high_noise) | Q5_1 | 11.01 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q5_1.gguf (low_noise) | Q5_1 | 11.01 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q5_K_M.gguf (high_noise) | Q5_K_M | 10.79 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q5_K_M.gguf (low_noise) | Q5_K_M | 10.79 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q5_0.gguf (high_noise) | Q5_0 | 10.31 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q5_0.gguf (low_noise) | Q5_0 | 10.31 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q5_K_S.gguf (high_noise) | Q5_K_S | 10.14 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q5_K_S.gguf (low_noise) | Q5_K_S | 10.14 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q4_K_M.gguf (high_noise) | Q4_K_M | 9.65 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q4_K_M.gguf (low_noise) | Q4_K_M | 9.65 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q4_1.gguf (high_noise) | Q4_1 | 9.26 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q4_1.gguf (low_noise) | Q4_1 | 9.26 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q4_K_S.gguf (high_noise) | Q4_K_S | 8.75 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q4_K_S.gguf (low_noise) | Q4_K_S | 8.75 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q4_0.gguf (high_noise) | Q4_0 | 8.56 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q4_0.gguf (low_noise) | Q4_0 | 8.56 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q3_K_M.gguf (high_noise) | Q3_K_M | 7.17 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q3_K_M.gguf (low_noise) | Q3_K_M | 7.17 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q3_K_S.gguf (high_noise) | Q3_K_S | 6.51 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q3_K_S.gguf (low_noise) | Q3_K_S | 6.51 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-HighNoise-Q2_K.gguf (high_noise) | Q2_K | 5.30 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
| Wan2.2-T2V-A14B-LowNoise-Q2_K.gguf (low_noise) | Q2_K | 5.30 GB | QuantStack/Wan2.2-T2V-A14B-GGUF → |
MoE of two 14B experts (27B total, 14B active per step): high-noise model for early steps, low-noise for late steps, run sequentially. Only one needs to be in VRAM at a time if ComfyUI offloads between them, but both must fit in system RAM (or be reloaded from disk). Disk = 2x file size. Text encoder umt5_xxl; VAE is Wan 2.1 VAE.