Image editing means you give the model a photo and tell it what to change: “make the shirt red”, “remove the car”, “turn it into a watercolour”. The two models people use for this in ComfyUI are FLUX.1 Kontext [dev] and Qwen-Image-Edit 2511. I ran both on my RTX 5060 Ti 16 GB (32 GB RAM, ComfyUI 0.38.1) with the same photo and the same instruction.
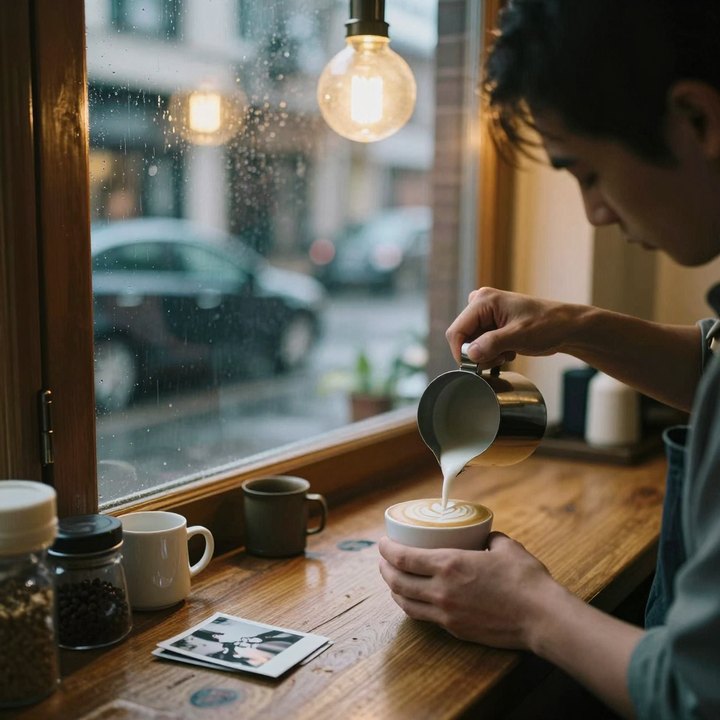
Same photo, same instruction
Instruction: “Change the barista's shirt to a bright red knitted sweater. Keep everything else the same.” Seed 42, first result, no cherry-picking.
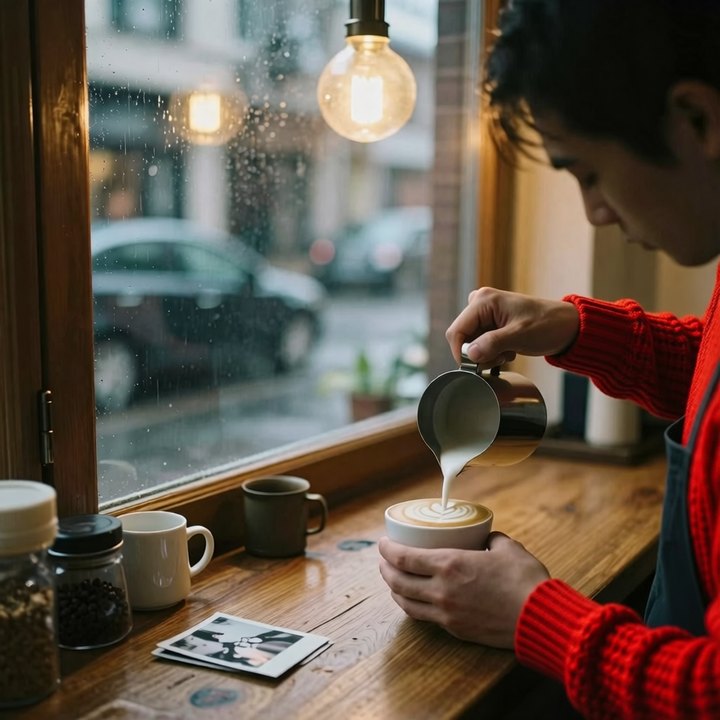
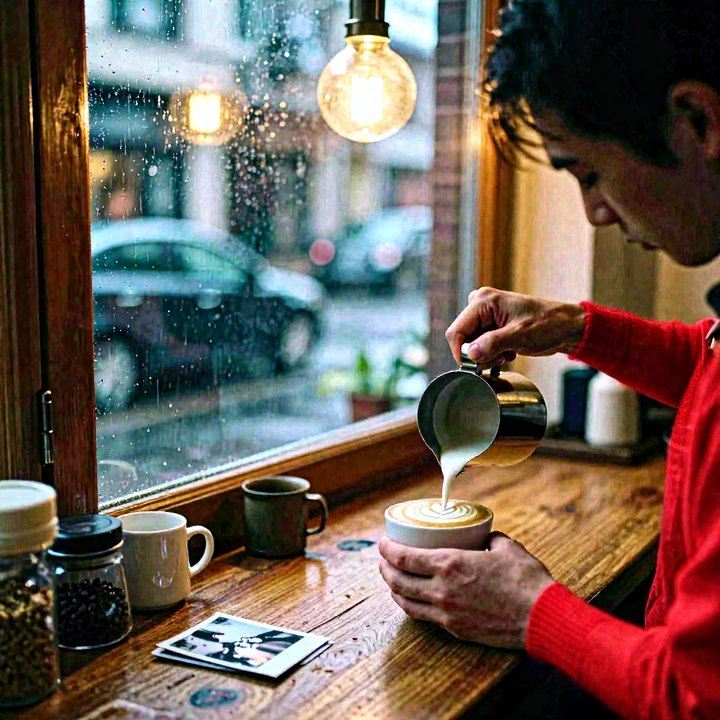
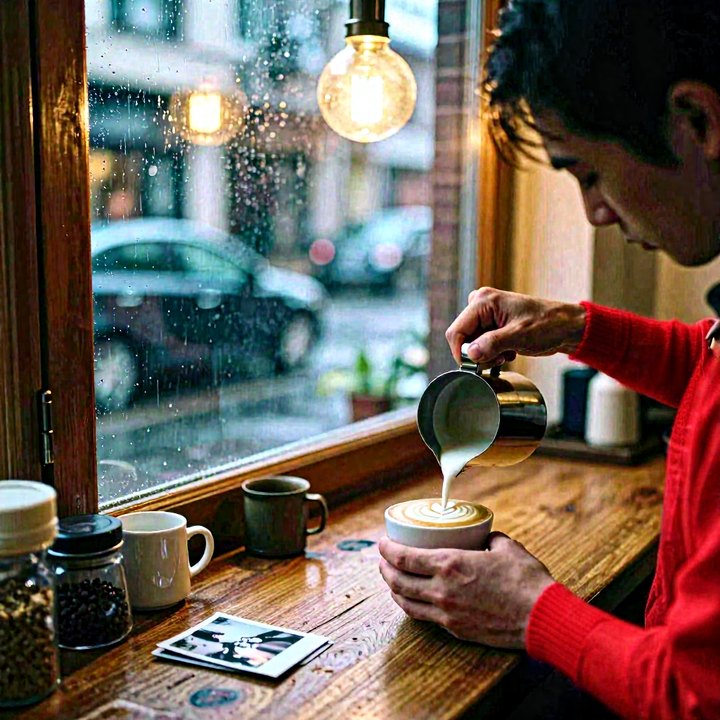
Speed, memory and licence
| Model and file | Per edit | Peak VRAM | Model file | Licence | |
|---|---|---|---|---|---|
| Qwen-Image-Edit GGUF Q4_K_M + 4-step LoRA | 27.2 s | 15.9 GB | 13.2 GB | Open | Workflow → |
| FLUX.1 Kontext FP8 | 53.3 s | 15.0 GB | 11.9 GB | Non-commercial | Workflow → |
| FLUX.1 Kontext GGUF Q8_0 | 82.1 s | 15.5 GB | 12.7 GB | Non-commercial | Workflow → |
About 1024×1024, average of 2 runs after a warm-up, sampling plus VAE decode. Peak VRAM is the whole card. Qwen-Image-Edit uses the 4-step Lightning LoRA here.
Why the Lightning LoRA matters on 16 GB
I also ran Qwen-Image-Edit the official way: 40 steps, CFG 4, no LoRA. With CFG the model works on two copies of the image at once, so it needs more memory. On my 16 GB card the video memory filled up completely. When that happens on Windows, the NVIDIA driver usually starts using system RAM instead (Sysmem Fallback), and everything slows to a crawl. After 20 minutes the edit was still not done, and I stopped it. With the 4-step LoRA the same edit took 27 seconds.
So on 16 GB: use the Lightning LoRA, or a smaller file (Q3_K_M) if you want the full 40 steps. If a run is suddenly very slow instead of failing, read slow instead of out of memory.
Which one to pick
- You want to sell the results or use them at work: Qwen-Image-Edit 2511 is Apache-2.0. FLUX.1 Kontext [dev] is under the FLUX [dev] Non-Commercial License — see licences of all models.
- You have a smaller card: Kontext fits from 7 GB of VRAM with a small GGUF file; Qwen-Image-Edit needs 11 GB or more. Check your GPU for the exact file.
- Edits with text in the image (signs, labels, posters): Qwen-Image-Edit is known for this; its text encoder is a 7B vision-language model that also reads the input photo.
- Tip for both: say what to keep, not only what to change — “Keep everything else the same” helps a lot.
Files you need
Each workflow opens with a note that lists every file with a link and the folder it goes in. Download them from the free workflows page. The Qwen-Image-Edit text encoder is big (9.4 GB) and also needs system RAM: with 16 GB of RAM, close other programs.
All my timings: everything on the RTX 5060 Ti 16 GB. Text-to-image models side by side: best image model for 16 GB.