Most advice about FP8 and GGUF is copied from forum posts written for older GPUs and older ComfyUI versions. So I timed it on my own card: an RTX 5060 Ti 16 GB, the card I use every day for FLUX images.
The result
Seconds per 1024×1024 image, FLUX.1 [dev], 20 steps. Shorter is better.
| File type | File | Size | Per image | Range | Peak VRAM |
|---|---|---|---|---|---|
| FP8 | flux1-dev-fp8.safetensors | 11.9 GB | 36.4 s | 36.0–37.1 s | 14.8 GB |
| GGUF Q8_0 | flux1-dev-Q8_0.gguf | 12.7 GB | 40.6 s | 40.5–40.7 s | 15.1 GB |
| GGUF Q4_K_S | flux1-dev-Q4_K_S.gguf | 6.8 GB | 47.3 s | 47.2–47.4 s | 8.8 GB |
Average of 3 timed runs after 1 warm-up run. Peak VRAM is the memory in use on the whole card during the run, including Windows and the text encoder.
The three pictures
Same prompt, same seed (42), same settings; only the file changed. The prompt asked for a cabin at dusk with a small wooden sign that says “VRAM READY”.
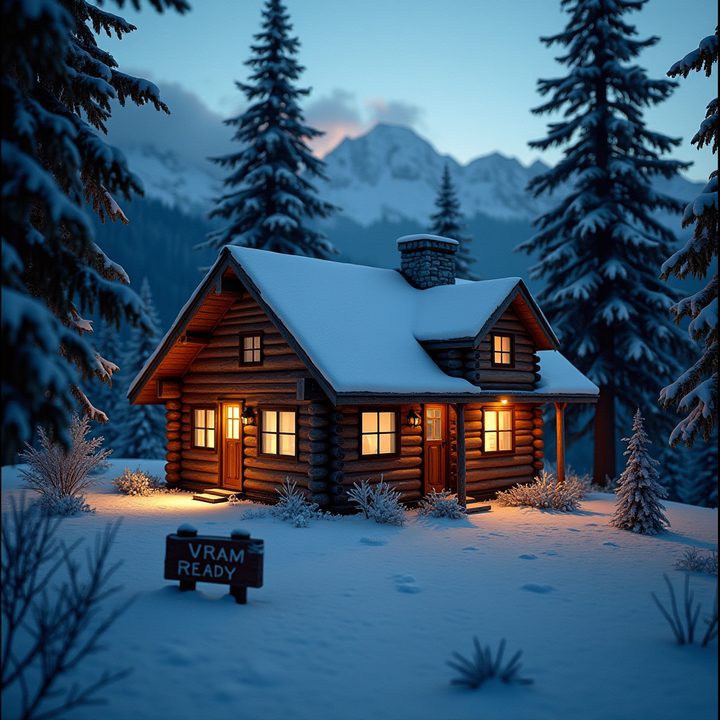
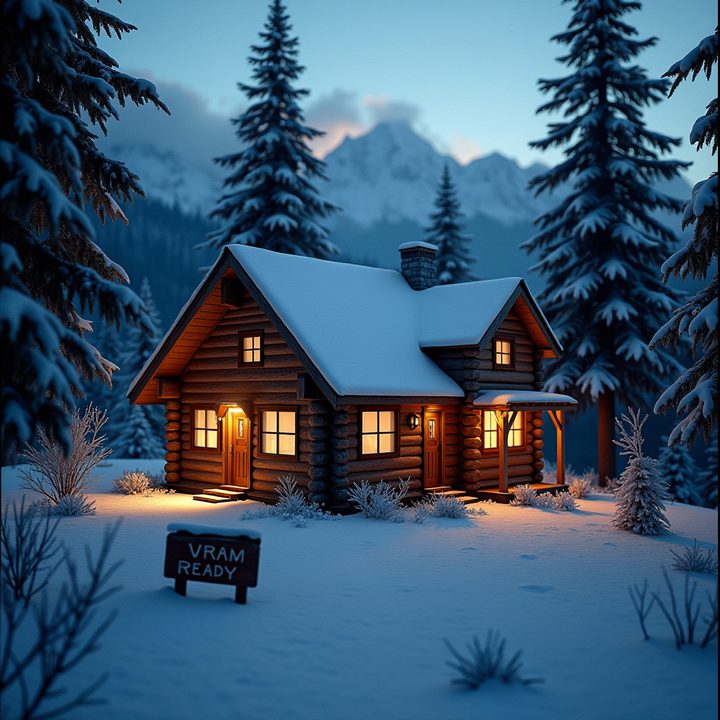
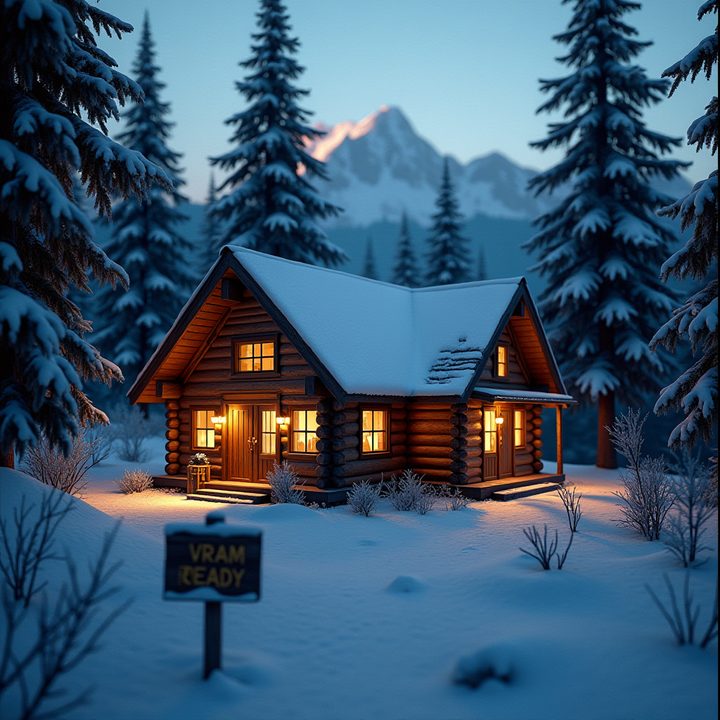
FP8 and Q8_0 drew almost the same picture: the same cabin and the same sign, with small differences in the trees and the snow. Q4_K_S drew a different picture from the same seed. The cabin is turned, and the sign stands on one post and is out of focus. With a smaller file it is not only the fine detail that changes; the whole image can come out different.
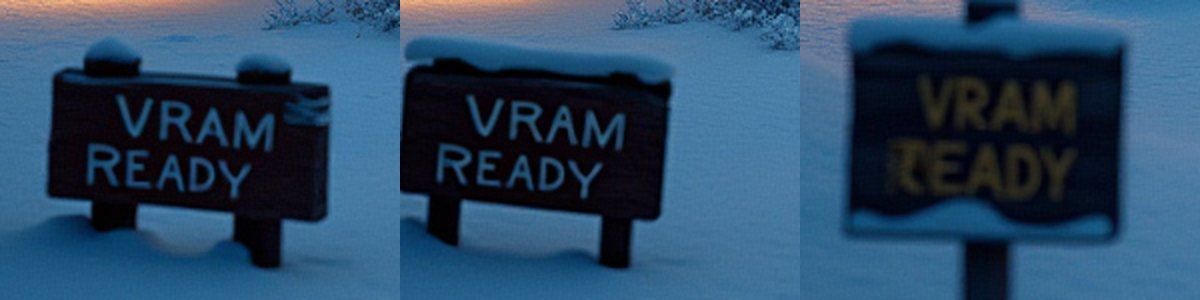
On the Q4_K_S sign the R at the start of READY is smudged. One image is not a rule, but if your pictures need clean text, I would stay with an 8-bit file.
What it means
- FP8 is the fastest on an RTX 50 card. Q8_0 is almost the same size but was 12% slower. RTX 40 and RTX 50 GPUs compute FP8 in hardware; GGUF weights have to be unpacked at every step.
- Q4_K_S saves a lot of memory: about 6 GB less in use on the card. It costs 30% more time per image, and some fine detail.
- On a 16 GB card, take FP8 for FLUX.1 [dev]. Use Q4_K_S (or Q5/Q6) only if you need the memory for something else at the same time: LoRAs, ControlNet, a bigger resolution, or a second model.
On RTX 30 or older, and on AMD RX 7000 or Intel Arc, there is no FP8 compute, so this result does not carry over. There, Q8_0 is usually the better 8-bit choice. See FP8, GGUF or 16-bit for the full picture.
For comparison, FLUX.1 [schnell] Q8_0 at 4 steps took 9.4 s per image on the same card.
My setup
- GPU: NVIDIA GeForce RTX 5060 Ti 16 GB, desktop. System RAM: 32 GB.
- ComfyUI 0.25.0 portable (Windows), PyTorch 2.12 with CUDA 13.0, default launch options.
- Text encoders: T5-XXL FP8 + CLIP-L. VAE: ae.safetensors. Sampler euler, scheduler simple, guidance 3.5, CFG 1.
- GGUF files loaded with the ComfyUI-GGUF
Unet Loader (GGUF)node; the FP8 file with the normalLoad Diffusion Modelnode. - Time is measured by ComfyUI from start to end of the job: sampling plus VAE decode. The prompt stays the same, so the text encoder output is reused between runs.
- Date: 2026-09-27.
More results from my card are on the RTX 5060 Ti 16 GB page and on all measured and reported results. If you have run the same test on another GPU, send me your numbers.